Automatic Thread Configuration#
This chapter introduces how RonDB handles automatic thread configuration.
With automatic thread configuration it is possible to scale RonDB data nodes up and down in an easy manner. It is possible to start the data node with access to e.g. 4 CPUs and later scale it to 8 CPUs and even later again scaling it to 16 CPUs. With RonDB running in a cloud environment this feature makes it very easy to manage RonDB to handle higher workloads as need arises.
This chapter is more technical and dives deeper under the surface of how RonDB operates. RonDB provides a configuration option, ThreadConfig, whereby the user can have full control over the assignment of threads to CPUs, how the CPU locking is to be performed and how the thread should be scheduled.
However for the absolute majority of users this is too advanced, thus the managed version of RonDB ensures that this thread configuration is based on best practices found over decades of testing. This means that every user of the managed version of RonDB will get access to a thread configuration that is optimised for their particular VM size.
In addition RonDB makes use of adaptive CPU spinning in a way that limits the power usage, but still provides very low latency in all database operations. This improves latency by up to 50% and in most cases more than 10% improvement.
RonDB uses automatic thread configuration by default. This means that as a user you don’t have to care about the configuration of threads. What RonDB does is that it retrieves the number of CPUs available to the RonDB data node process. In the managed version of RonDB, this is the full VM or bare metal server available to the data node. In the open source version of RonDB one can also limit the amount of CPUs available to RonDB data nodes process by using taskset or numactl when starting the data node. RonDB retrieves information about CPU cores, CPU sockets and connections to the L3 caches of the CPUs. All of this information is used to set up the optimal thread configuration.
Thread types in RonDB#
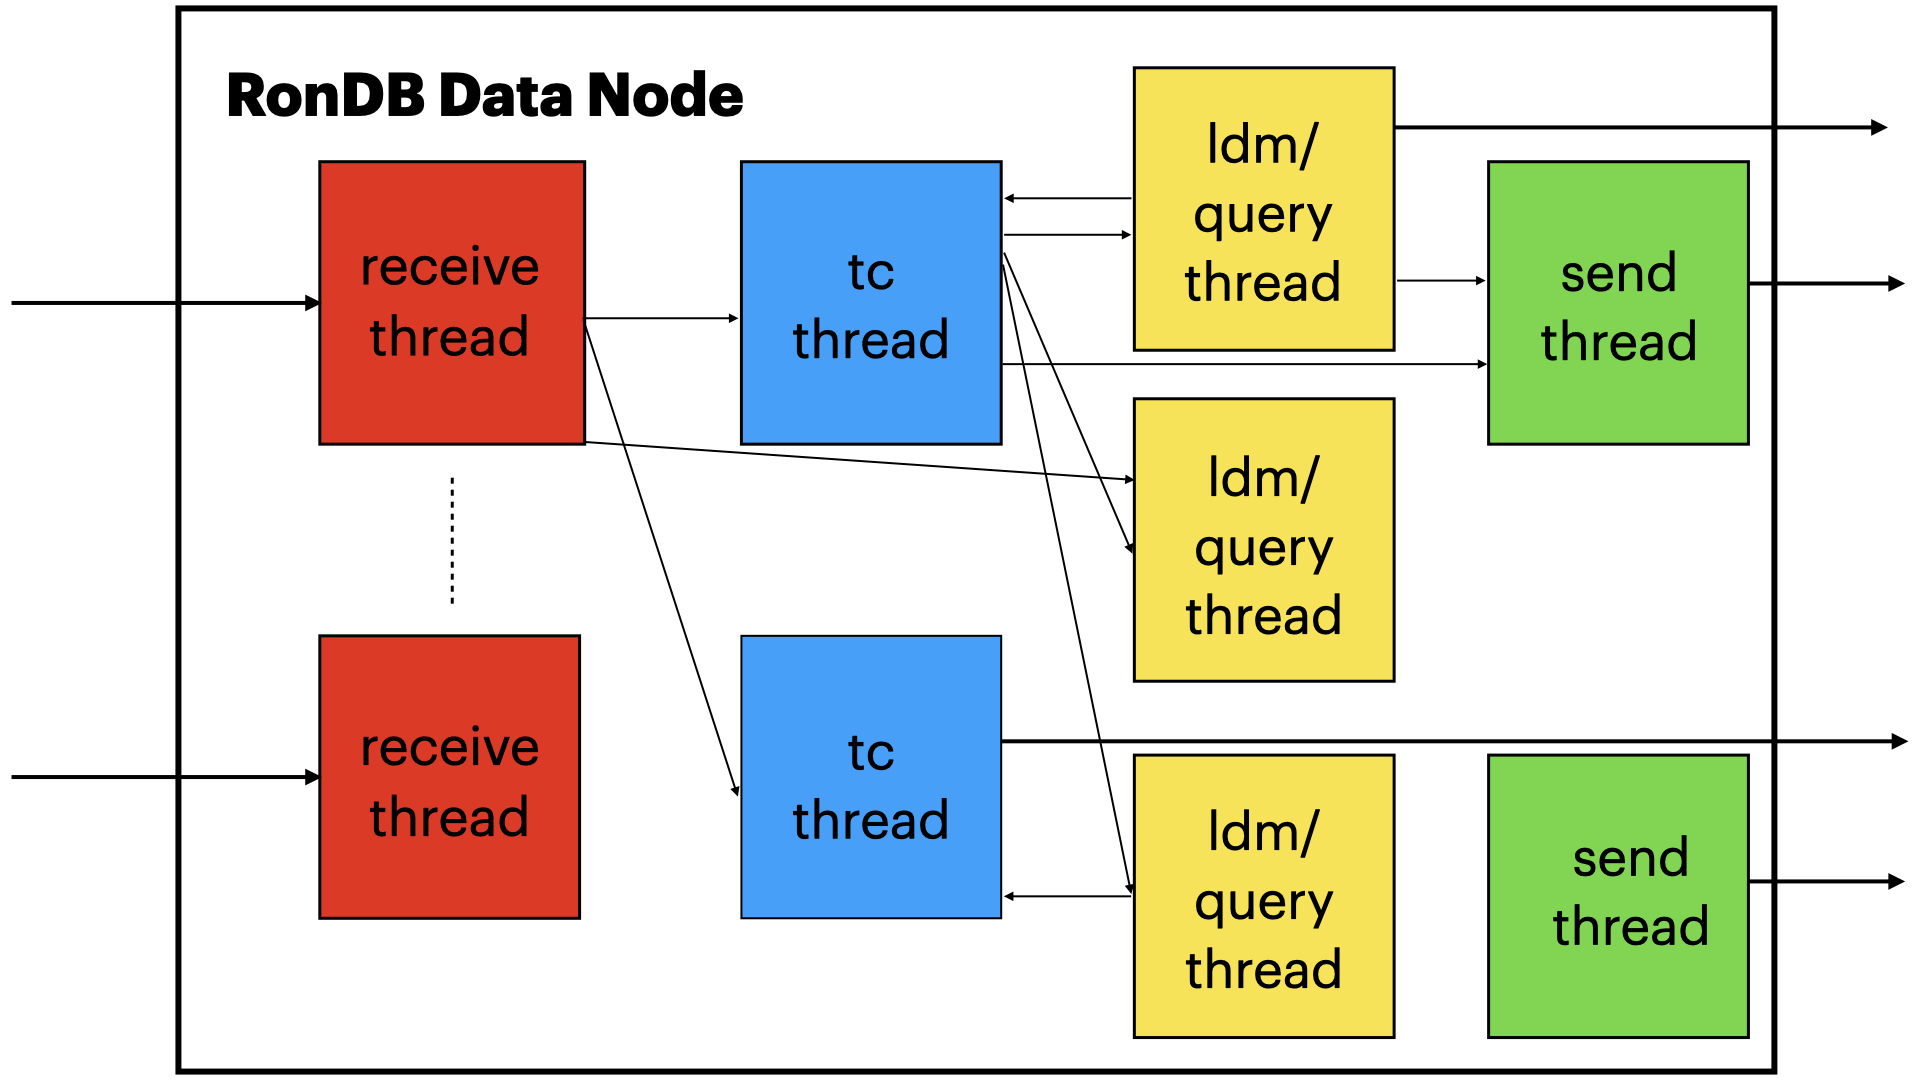
ldm threads that house the data, tc threads that handle transaction coordination, recv threads that handle receive of network messages, send threads that handle sending of network messages, and main threads that handle metadata operations, asynchronous replication and a number of other things. In addition every ldm, tc, main, rep and recv thread has a query worker that executes reads on data owned by ldm threads: read committed reads, and when it is safe also locked reads, which UseQueryThreadLockedReads controls.
ldm threads#
ldm thread is a key thread type. The ldm thread is responsible to read and write data. It manages the hash indexes, the ordered indexes, the actual data and a set of triggers performing actions for indexes, foreign keys, full replication, asynchronous replication. This thread type is where most of the CPU processing is done. RonDB has an extremely high number of instructions per cycle compared to any other DBMS engine. The ldm thread often executes 1.25 instructions per cycle where many other DBMS engines have reported numbers around 0.25 instructions per cycle. This is a key reason why RonDB has such a great performance both in terms of throughput and latency. This is the result of a design of data structures in RonDB that is CPU cache aware and the functional separation of thread types.
Query workers#
A table partition (sometimes referred to as a table fragment or shard) belongs to a certain ldm thread, thus only this ldm thread can be used for writes and most locked reads on rows in this table partition. Read committed reads, which a normal SELECT query uses, can also be executed by other threads, and when it is safe also locked reads, which UseQueryThreadLockedReads controls.
NDB Cluster 8.0.23 introduced query threads for this, a thread type that runs the same code as the ldm threads and executes reads. RonDB used one query thread per ldm thread up to RonDB 22.10. Since RonDB 24.10 there are no query threads. Instead every ldm, tc, main, rep and recv thread has a query worker. Thus all these threads can help with reads, and a read can be executed by a thread that has spare capacity.
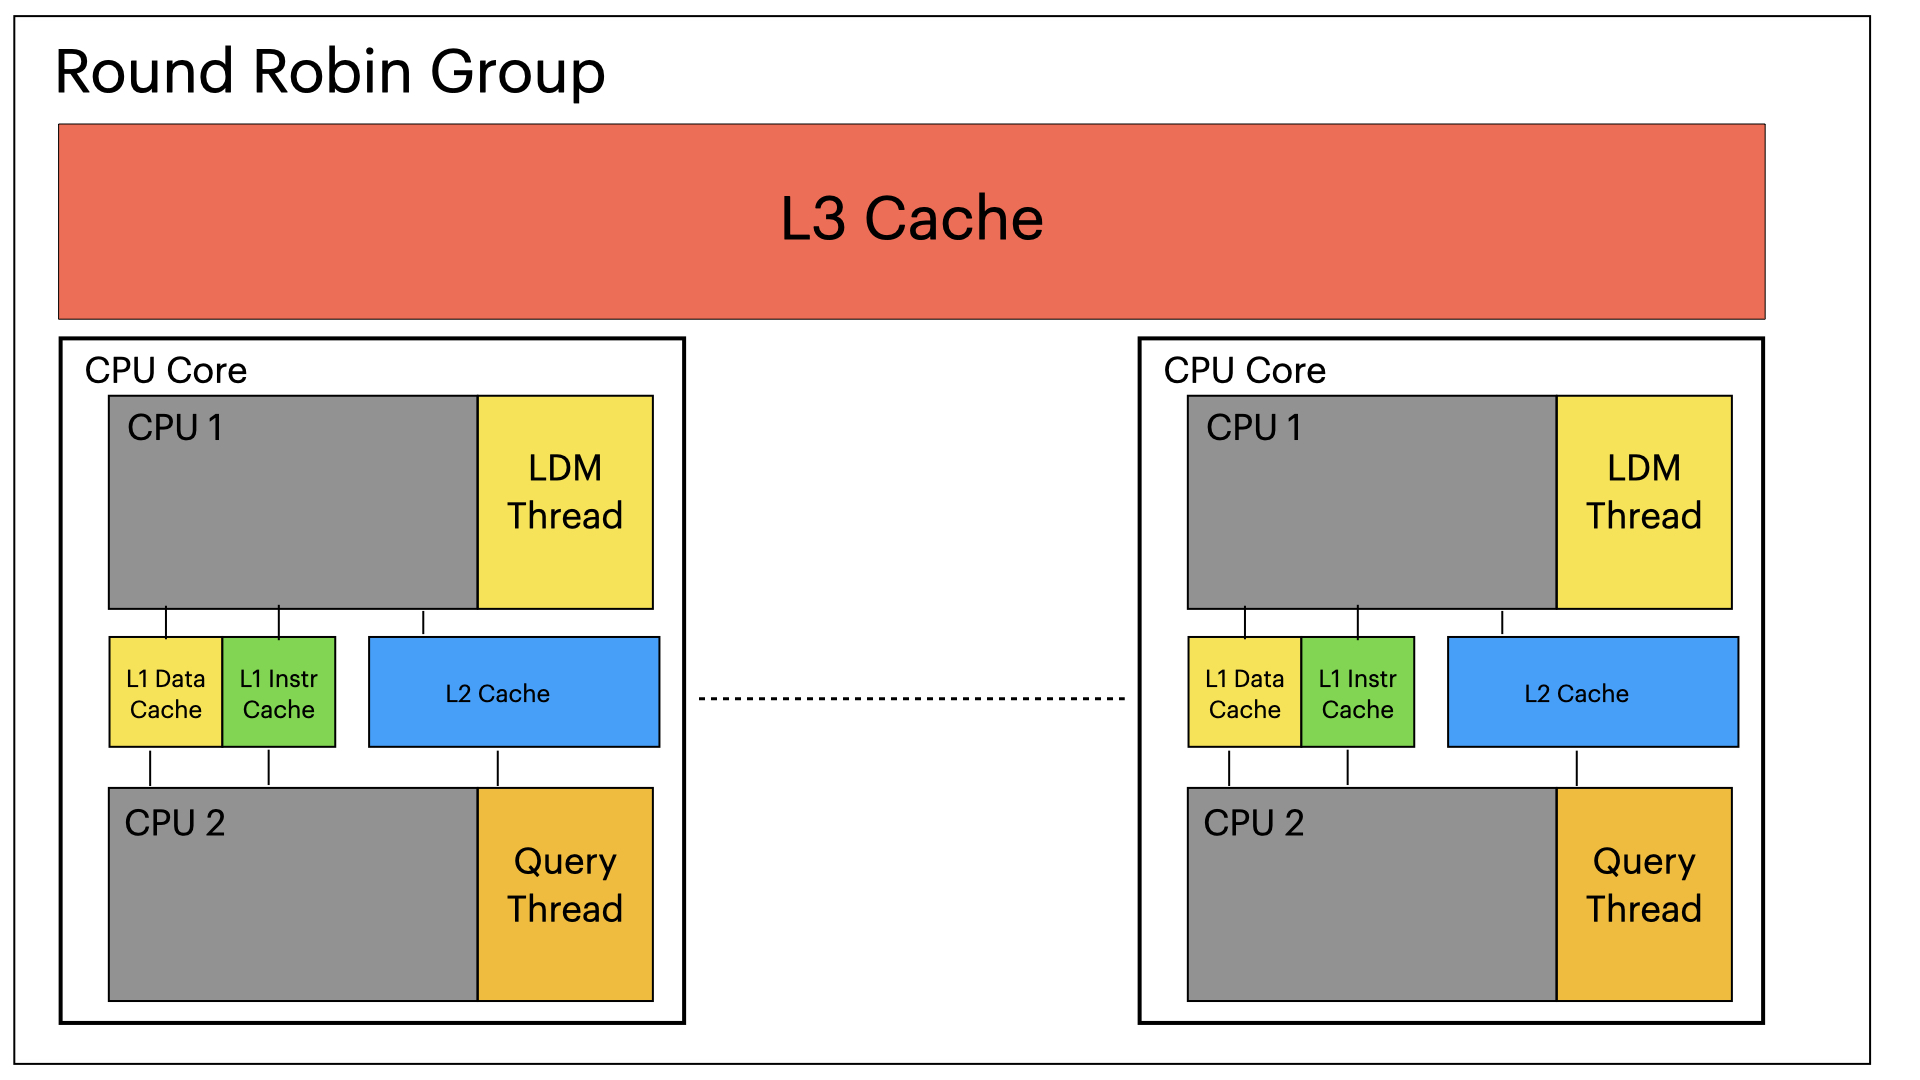
To achieve the best performance RonDB uses CPU locking. In Linux, it is quite common that a thread migrates from one CPU to another CPU. If the thread migrates to a CPU belonging to a different CPU core, the thread will suffer a lot from CPU cache misses immediately after being migrated. To avoid this RonDB lock threads to a certain CPU core. Thus it is possible to migrate the thread, but only to the other CPU in the CPU core that share the same CPU caches.
The threads are organised into Round Robin groups. All threads within one Round Robin group share the same CPU L3 cache. A read on the data of an ldm thread can only be executed by a query worker in the same Round Robin group as that ldm thread. This retains the CPU efficiency, since threads that share data structures and mutexes also share CPU caches. The size of a Round Robin group is set by MaxRRGroupSize, by default at most 8 query workers; a group has at least 4 query workers when there are enough of them.
Query workers make it possible to decrease the amount of partitions in a table. As an example, with query threads we were able to process more than 3 times as many transactions per second using a single partition in Sysbench OLTP RW compared to when we only used ldm threads.
Most key-value stores have data divided into table partitions for the primary key of the table. Many key-value stores also contain additional indexes on columns that are not used for partitioning. Since the table is partitioned, this means that each table partition will contain each of those additional indexes.
When performing a range scan on such an index, each table partition must be scanned. Thus the cost of performing range scans increases as the number of table partitions increases. RonDB can scale the reads in a single partition to many query workers, this makes it possible to decrease the number of table partitions in RonDB. In Sysbench OLTP RW this improves performance by around 20% even in a fairly small 2-node setup of RonDB.
In addition query workers ensure that hotspots in the tables can be handled by many threads, thus avoiding the need to partition even more to handle hotspots.
At the same time a modest amount of table partitions increases the amount of writes that we can perform on a table and it makes it possible to parallelise range scans which will speed up complex query execution significantly. Thus in RonDB we have attempted to find a balance between overhead and improved parallelism and improved write scalability.
Costs of key lookups are not greatly affected by the number of partitions since those use a hash lookup and thus always go directly to the thread that can execute the key lookup.
On CPUs with two hyperthreads per CPU core, RonDB places two ldm threads on the same CPU core where it can. When a CPU core has one ldm thread and one other thread, the other thread is a tc thread.
A common choice for a scheduling algorithm in an architecture like this would be to use a simple round robin scheduler. However such an algorithm is too simple for this model. We have two problems to overcome. The first is that the load on ldm threads is not balanced since we have decreased the number of table partitions in a table. Second writes and locked reads can only be scheduled in an ldm thread. Thus it is important to use the Read Committed queries to achieve a balanced load.
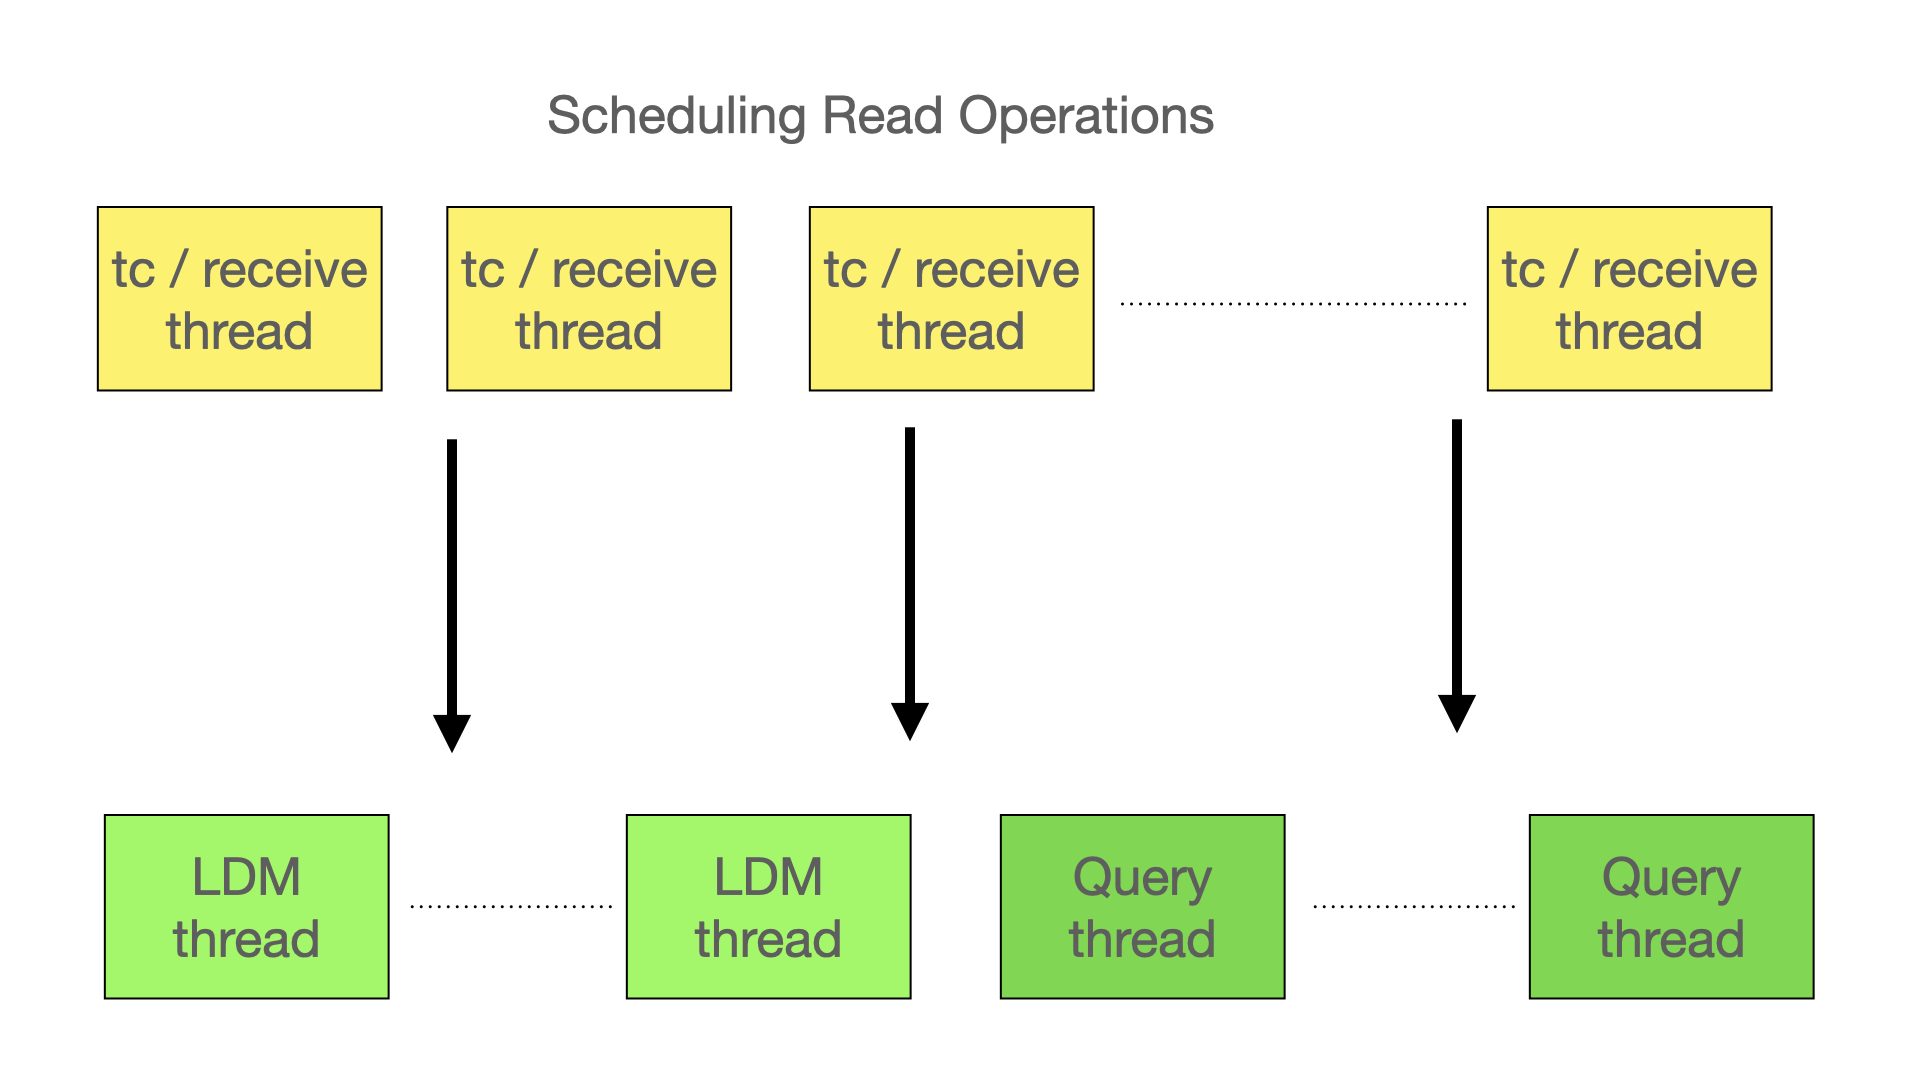
Given that we use less table partitions in RonDB compared to other solutions, there is a risk of imbalanced load on the CPUs. This is solved by a two-level load balancer. Every 100 milliseconds the data node gives each thread a weight based on its CPU load. In addition each thread reports a load indicator, based on its queues, every few hundred microseconds. When the data node has a low load, a read is executed by the ldm thread that owns the data. Otherwise a read first tries the owning ldm thread and the thread on the same CPU core, and when those have used up their weights, it goes to the other query workers in the Round Robin group in proportion to their weights. A thread with a higher load indicator gets a smaller share. Thus work moves away from overloaded threads to threads with spare capacity.
About half of the CPUs run ldm threads.
tc threads#
The tc threads receive all database operations sent from the NDB API. It takes care of coordinating transactions and decides which node should take care of the queries. It uses around 20-25% of the CPU resources. Unless the application asks for a specific tc thread, the data node chooses one for each new transaction record: by default a tc thread in the Round Robin group of the recv thread that received the request, see UseTcInRRGroup below.
recv threads#
The recv threads take care of a subset of the communication links. Thus the recv thread load is usually fairly balanced but can be a bit more unbalanced if certain API nodes are more used in querying RonDB. The communication links between data nodes in the same node group are heavily used when performing updates. To ensure that RonDB can scale in this situation these node links use multiple communication links. recv threads use around 10-15% of the CPU resources.
send threads#
The send threads assist in sending networking messages to other nodes. The sending of messages can also be done by the ldm, tc, main and rep threads, and by the recv threads when there are no ldm threads, and there is an adaptive algorithm that assigns more load for sending to threads that are not so busy. The send threads assists in sending to ensure that we have enough capacity to handle all the load. It is not necessary to have send threads, the threads can handle sending even without a send thread. However the adaptive send support relies on using at least one send thread. send threads use around 5 to 10% of the CPUs available. The main threads provide extra send support when the send threads are loaded to 75% or more.
The total cost of sending can be quite substantial in a distributed database engine, thus the adaptive algorithm is import to balance out this load on the various threads in the data node.
main threads#
The main threads can be 0, 1 or 2. These threads handle a lot of the interactions around creating tables, indexes and any other metadata operation. They also handle a lot of the code around recovery and heartbeats. They are handling any subscriptions to asynchronous replication events used by replication channels to other RonDB clusters.
Internally the main threads are called main and rep thread. If there is only one thread then all actions for both thread types are handled by this single thread and if no main thread is used, the actions are handled by the recv thread.
Number of threads of each type#
The number of threads of each type depends on the number of CPUs. This is the number of CPUs that the data node process can use, or NumCPUs when it is set, minus the CPUs reserved by ExclusiveIoCPUs. Up to 48 CPUs the numbers come from a table, shown below for even numbers of CPUs. An odd number of CPUs, except 1, gets one more recv thread than the even number below it.
| CPUs | ldm | tc | recv | send | main | rep |
|---|---|---|---|---|---|---|
| 1 | 0 | 0 | 1 | 0 | 0 | 0 |
| 2 | 0 | 0 | 2 | 0 | 0 | 0 |
| 4 | 0 | 0 | 4 | 0 | 0 | 0 |
| 6 | 0 | 0 | 5 | 1 | 0 | 0 |
| 8 | 4 | 2 | 1 | 1 | 0 | 0 |
| 10 | 4 | 3 | 1 | 1 | 1 | 0 |
| 12 | 6 | 3 | 1 | 1 | 1 | 0 |
| 14 | 6 | 4 | 2 | 1 | 1 | 0 |
| 16 | 8 | 4 | 2 | 1 | 1 | 0 |
| 18 | 8 | 4 | 3 | 1 | 1 | 1 |
| 20 | 8 | 5 | 3 | 2 | 1 | 1 |
| 22 | 10 | 5 | 3 | 2 | 1 | 1 |
| 24 | 10 | 6 | 4 | 2 | 1 | 1 |
| 26 | 12 | 6 | 4 | 2 | 1 | 1 |
| 28 | 12 | 8 | 4 | 2 | 1 | 1 |
| 30 | 14 | 8 | 4 | 2 | 1 | 1 |
| 32 | 16 | 8 | 4 | 2 | 1 | 1 |
| 34 | 16 | 9 | 5 | 2 | 1 | 1 |
| 36 | 18 | 9 | 5 | 2 | 1 | 1 |
| 38 | 18 | 10 | 5 | 3 | 1 | 1 |
| 40 | 20 | 10 | 5 | 3 | 1 | 1 |
| 42 | 20 | 11 | 6 | 3 | 1 | 1 |
| 44 | 22 | 11 | 6 | 3 | 1 | 1 |
| 46 | 22 | 12 | 6 | 4 | 1 | 1 |
| 48 | 24 | 12 | 6 | 4 | 1 | 1 |
With up to 7 CPUs there are no ldm, tc, main and rep threads, and the recv threads do all their work.
With more than 48 CPUs the numbers come from a formula. With n CPUs there is one main and one rep thread, n/2 ldm threads, n/4 tc threads, n/8 recv threads and n/12 send threads, rounded down. The CPUs left over by the rounding go first to send threads, then to ldm, recv and tc threads. Finally, when the number of ldm threads is odd, one ldm thread becomes a send thread, so that the Round Robin groups stay balanced. As an example, 64 CPUs give 32 ldm, 16 tc, 8 recv and 6 send threads, and 96 CPUs give 48 ldm, 24 tc, 12 recv and 10 send threads.
When there are more than 32 block threads and send threads in total, the ldm and tc threads get nosend set, so they do not assist the send threads.
Algorithm to select CPU mapping of block threads#
Before we map the threads to CPUs we organise the CPUs in a list. The CPUs are grouped by the L3 cache they share, and these groups form the Round Robin groups. The list takes one CPU core, that is two CPUs next to each other, from each Round Robin group in turn. If we don’t have access to L3 cache information we treat all CPUs as sharing the same L3 cache, which is often true for many CPUs.
We then walk through the list and assign a thread to each CPU. The first CPU cores in the list run two ldm threads each, the same even number of ldm threads in each Round Robin group. After that, a CPU at an even position in the list, the first CPU of a CPU core, gets a thread of the first type in the order ldm, recv, main, send, rep and tc that has threads left. A CPU at an odd position gets a thread in the order tc, rep, recv and send. Thus where a CPU core has one ldm thread and one other thread, the other thread is a tc thread. The remaining CPU cores get a mix of tc and recv threads, with the main, rep and send threads towards the end of the list.
The ldm thread instances are dealt to the Round Robin groups in turn, so that consecutive ldm threads belong to different Round Robin groups. A table places its partitions on consecutive ldm threads, so a table with several partitions can use the query workers of several Round Robin groups.
The aim of the algorithm selecting the CPU mapping is to have about half the CPUs used by ldm threads, about 25% assigned as tc threads, about 12.5% as recv threads and the rest for send, main and rep threads. However whether this is achieved depends on the CPUs made available to the RonDB data nodes.
Configuration parameters#
Automatic thread configuration is used when AutomaticThreadConfig is set, which is the default. ThreadConfig and MaxNoOfExecutionThreads are then ignored; ThreadConfig is only used when AutomaticThreadConfig is set to 0. The following parameters adjust automatic thread configuration. They seldom need to be changed.
UseLdmThreads and UseTcThreads#
By default the data node has ldm threads and tc threads. With UseTcThreads set to false, the CPUs that would run tc threads run recv threads instead, and each recv thread also does the work of a tc thread. With UseLdmThreads set to false, the CPUs of the ldm, tc, main and rep threads all run recv threads, and each recv thread also does the work of an ldm thread and a tc thread. Both default to true, and both are only used with automatic thread configuration. Setting them to false is mainly intended for performance analysis and debugging.
MaxRRGroupSize#
Round Robin groups decide which threads can execute reads on the data of an ldm thread, and which tc thread a recv thread prefers. MaxRRGroupSize is the size of a Round Robin group, counted in threads that execute queries. When RonDB knows which CPUs share an L3 cache, it is the target size of the groups formed in each L3 cache region; otherwise the threads are divided into groups of at most this size. The default is 8 and the range 8 to 32.
UseTcInRRGroup#
When an API node allocates a transaction record in a data node, the recv thread that receives the request chooses the tc thread for it. With UseTcInRRGroup set to true, the default, it chooses a tc thread in its own Round Robin group. With false it chooses among all tc threads in round robin order.
KeyBatchSizeQueryWorker and ScanBatchSizeQueryWorker#
When reads are spread over the query workers of a Round Robin group, a number of requests in a row go to the same worker before the next worker is used. KeyBatchSizeQueryWorker sets this number for key lookups, by default 4 with the range 1 to 64. ScanBatchSizeQueryWorker sets it for fragment scans, by default 1 with the range 1 to 16.
UseQueryThreadLockedReads#
With UseQueryThreadLockedReads set to false, a locked read sent in a batch together with other operations is always executed by the ldm thread that owns the data, on the primary replica. With true, the default, such a read can also be executed by a query worker when it is safe. Read committed reads are not affected.
ExclusiveIoCPUs#
Reserves a number of CPUs for the io threads, which also rebuild indexes during restarts. The other threads are not bound to these CPUs, while the io threads can use all CPUs. This can make restarts faster. The default is 0 and the maximum 8, and at most a quarter of the CPUs are reserved. It is only used when RonDB knows the CPU layout and NumCPUs is not set.
ClassicFragmentation#
With automatic thread configuration, the number of partitions of a table is set by PartitionsPerNode, and ClassicFragmentation is ignored. Without automatic thread configuration, setting ClassicFragmentation to true gives each table as many partitions per node as the smallest number of ldm threads in a data node. The default is false.
Comparison of RonDB thread model#
Background#
RonDB is based on NDB Cluster. NDB was focused on being a high-availability key-value store from its origin in database research in the 1990s. The thread model in NDB is inherited from a telecom system developed in Ericsson called AXE. Interestingly in one of my first jobs, I worked at Philips on a banking system developed in the 1970s, this system had a very similar model compared to the original thread model in NDB and in AXE. In the operating system development time-sharing has been the dominant model since a long time back. However the model used in NDB where the execution thread is programmed as an asynchronous engine where the application handles a state machine has a huge performance advantage when handling many very small tasks. A normal task in RonDB is a key lookup, or a small range scan. Each of those small tasks is actually divided even further when performing updates and parallel range scans.
This means that the length of a task in RonDB is on the order of 500 ns up to around 10 microseconds. A normal time-sharing operating system would perform terribly in such an environment, both with regard to latency as well as in throughput. In the early days the competitors still used time-sharing OSs as their base and NDB would often outperform its competitors by a magnitude. RonDB still outperforms its competitors, but now the thread model is only one of the reasons for the outstanding throughput and latency.
Traditional thread design for key-value stores#
Time-sharing operating systems are not designed to handle context switches of this magnitude. NDB was designed with this understanding from the very beginning. Early competitors of NDB used normal operating system threads for each transaction and even in a real-time operating system this had no chance to compete with the effectiveness of NDB. None of these competitors are still around competing in the key-value store market.
Asynchronous thread model#
The first thread model in NDB used a single thread to handle everything, send, receive, database handling and transaction handling. This is version 1 of the thread architecture, this is implemented also in the open source version of Redis. With the development of multi-core CPUs it became obvious that more threads were needed. What NDB did here was introduce both a functional separation of threads and partitioning the data to achieve a more multi-threaded execution environment. This is version 2 of the thread architecture.
Modern competitors of RonDB have now understood the need to use asynchronous programming to achieve the required performance in a key-value store. We see this in AeroSpike, Redis, ScyllaDB and many other key-value stores. Thus the industry has followed the RonDB road to achieving an efficient key-value store implementation.
Functional separation of threads#
Most competitors have opted for only partitioning the data and thus each thread still has to execute all the code for meta data handling, replication handling, send, receive and database operations. Thus RonDB has actually advanced version 2 of the thread architecture further than its competitors.
One might ask, what difference does this make?
All modern CPUs use both a data cache and an instruction cache. By combining all functions inside one thread, the instruction cache will have to execute more code. In RonDB the ldm thread only executes the operation to change the data structures, the tc thread only executes code to handle transactions and the recv thread can focus on the code to execute network receive operations. This makes each thread more efficient. The same is true for the CPU data cache. The ldm thread need not bother with the data structures used for transaction handling and network receive. It can focus the CPU caches on the requirements for database operations which is challenging enough in a database engine.
This focus has enabled us to achieve an IPC of beyond 1.25 for the ldm threads which executes most of the instructions in RonDB.
A scalable key-value store design#
A simple splitting of data into different table partitions makes sense if all operations towards the key-value store are primary key lookups or unique key lookups. However most key-value stores also require performing general search operations as part of the application. These search operations are implemented as range scans with search conditions, these scale not so well with a simple splitting of data.
To handle this RonDB introduces version 3 of the thread architecture that uses a compromise where we still split the data, but we introduced query threads to assist the ldm threads in reading the data. Thus RonDB can handle hotspots of data and require fewer number of table partitions to achieve the required scalability of the key-value store.
RonDB 24.10 introduced version 4 of the thread architecture. It replaces the query threads with a query worker in every ldm, tc, main, rep and recv thread, so that all these threads can assist the ldm threads in reading the data. This means we can double the number of ldm threads and thus double the write throughput, while idle non-ldm threads assist in read queries.
However recv threads need sufficient time to receive. If signals have arrived and no recv thread is ready to receive them, other threads sit idle waiting for work. To find a balance the read scheduler aims for a CPU load on the recv threads that is 10 percentage points lower than on the ldm threads.
Finally, even if a competitor managed to replicate all of those features of RonDB, RonDB has another ace in the 3-level distributed hashing algorithm that makes use of a CPU cache aware data structure.
In addition we make heavy reuse of code paths in the critical database parts of the code. This means that the write code use to a great extent the same code that reads use. This again decreases the size of the code executed for database operations and ensures that we manage to handle the operations within the size of the instruction caches to a great extent.
Conclusion#
All of those things combined makes us comfortable that RonDB will continue to lead the key-value store market in terms of lowest Latency, highest Availability, the highest Throughput and the most Scalable data storage. Thus, being the best LATS database in the industry.
LATS = Latency Availability Throughput Scalable storage